Documents & drawings
Extract information from emails too.
DocsHero
HEROextractor makes information from documents, drawings and emails usable in your processes. Cloud AI recognises content, extracts relevant fields and provides structured data for further processing.
HEROextractor · Intelligent data extraction
Recognise information. Work with structured data. HEROextractor makes content from documents, drawings and emails usable in your processes.
Extract information from emails too.
Recognise content and extract relevant fields.
For your systems and next process steps.
Choose a document type and explore the process. Sample data is fictional; no files are uploaded or actually processed.
SAMPLE LTD Industriestraße 12 80953 Munich
Invoice date: 14 March 2024
Supply of technical components
| Description | Quantity | Unit price | Amount |
|---|---|---|---|
| Sensor module | 5 | EUR 160.00 | EUR 800.00 |
| Assembly kit | 1 | EUR 250.42 | EUR 250.42 |
Net amountEUR 1,050.42
VAT 19%EUR 199.58
Payment due within 14 days.
| Data field | Example value |
|---|---|
| Invoice number | INV-2048 |
| Total amount | EUR 1,250.00 |
| Supplier ID | S-1042 |
Select a field on the left to highlight its matching value.
Classification distinguishes document types. Recognition of print and handwriting makes content available for further processing.
Use the Training & Testing Suite to adapt document layouts, field inheritance and classifications to your needs. Test representative inputs and compare results before going live.
Adapt customer-specific document layouts, field inheritance and classifications to your needs.
The Matching Suite compares extracted information with your master data via REST. Rules support the processing of specific cases.
Adapt models to specific cases with rules, without requiring a new training run for every adjustment.
Match and validate extracted information against master data from third-party systems or databases via REST interfaces.
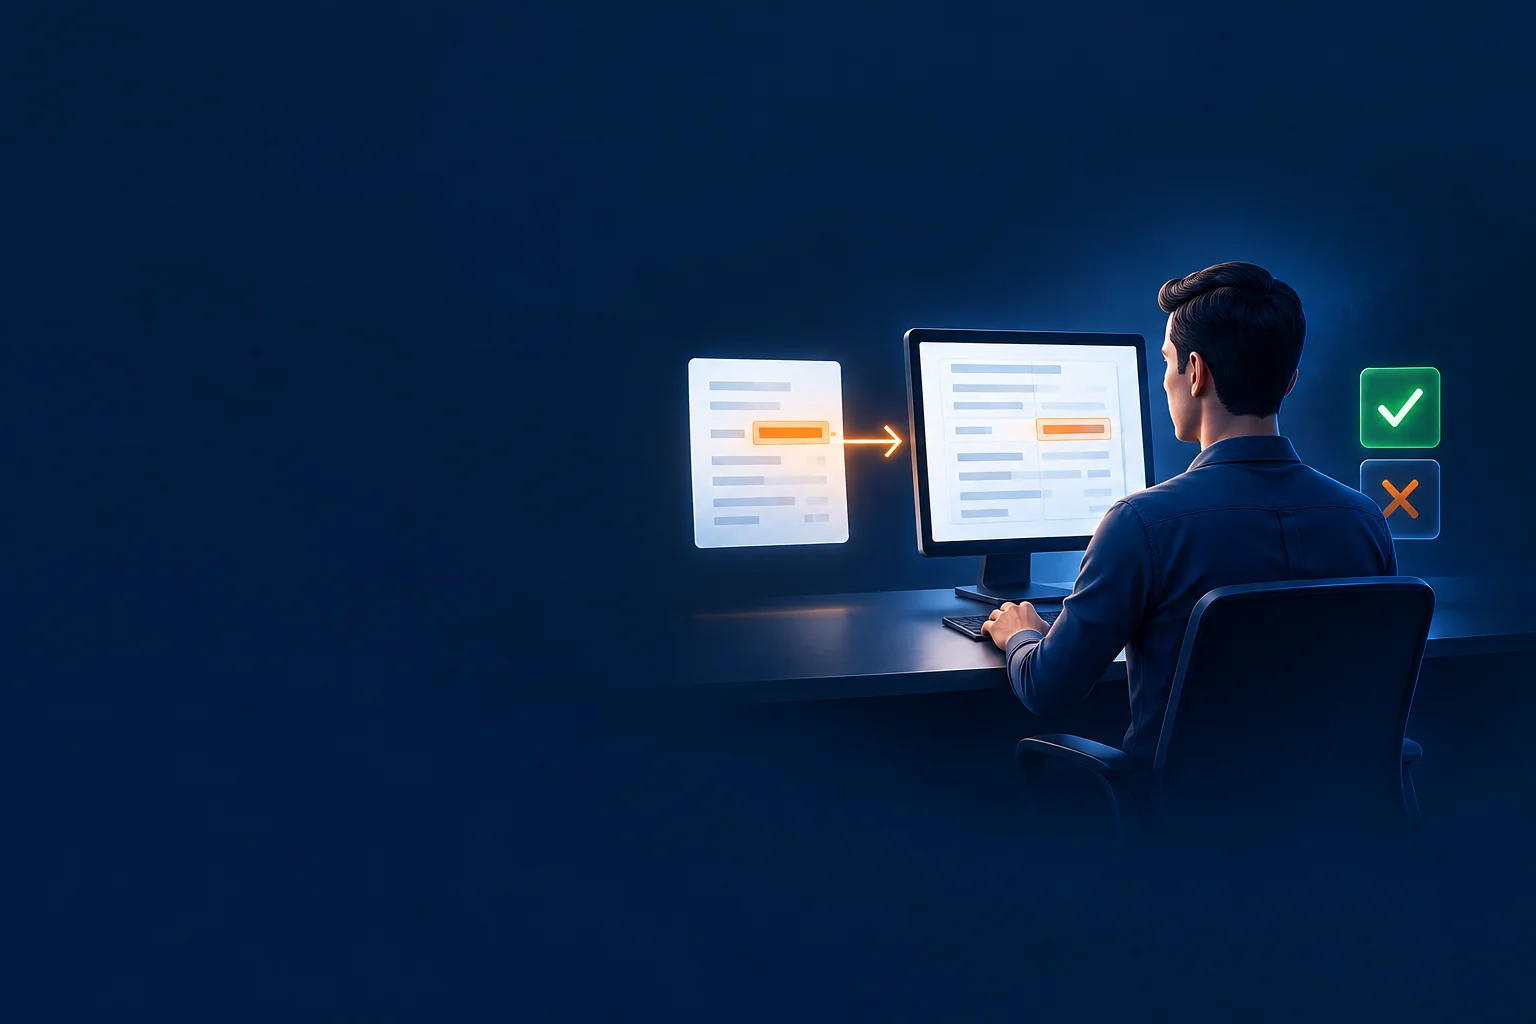
Review results and resolve anomalies before data moves to the next process step.
Define inputs, required fields and target systems together.
Use representative documents, test rules and agree measurable quality goals.
Configure data transfer, validation and operations for your business processes.
Discover how HEROextractor turns your documents into usable data.
Request a HEROextractor demoMore possibilities. For tomorrow.
Documents, drawings and emails. We use examples to determine the fields you need and formats suited to your use case.
Training and testing adapt recognition and classification to your inputs. The Rules Engine adds adjustments for specific cases without retraining each time.
The Matching Suite matches data with third-party systems and databases through REST interfaces. Data sources and checks are configured for your process.
Together we discuss data types, access rights, storage and deletion requirements, and privacy arrangements. Processing and operations are tailored to your use case.
Around 4.9 million documents: Classification foundation according to product information. Up to 500,000 document types: A broad foundation for varied inputs and use cases. 100 pages per second: Product performance figure. Actual throughput depends on documents, configuration and workload.
Loading form…